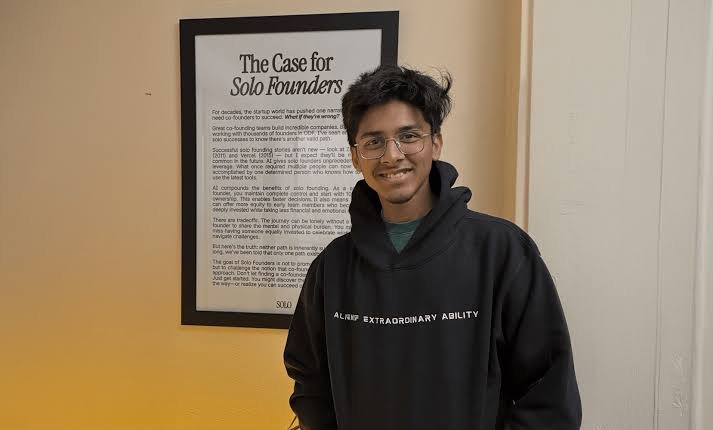
Dhravya Shah Success Story: From Mumbai Teen Builder to Supermemory Founder

Many founder stories begin with a business plan. Dhravya Shah’s journey began with small software projects and a habit of building quickly.
Originally from Mumbai, Shah created and sold software products while still in his teens. He later moved to the United States, studied at Arizona State University, worked on AI infrastructure at Cloudflare and eventually left college to build Supermemory full-time.
Supermemory provides memory and context infrastructure for AI applications and agents. In October 2025, the company announced its first funding round, officially describing it as a $3 million pre-seed investment.
The Dhravya Shah success story is not simply about raising money at a young age. It shows how repeated experiments, open-source work and technical experience can gradually reveal a larger business opportunity.
Dhravya Shah at a Glance
| Detail | Verified or reported information |
|---|---|
| Name | Dhravya Shah |
| Place of origin | Mumbai, India |
| Company | Supermemory |
| Role | Founder and CEO |
| Current company base | San Francisco |
| Education | Attended Arizona State University; later left to build full-time |
| Earlier work | Hypefury, AI-memory startup Mem0 and Cloudflare |
| Startup focus | Memory and continual-learning infrastructure for AI agents |
| Officially announced funding | $3 million pre-seed round |
| Lead investors named | Susa Ventures, Browder Capital and SF1.vc |
| Verified revenue or valuation | Not publicly disclosed |
Growing Up in Mumbai and Choosing to Build
Shah grew up in Mumbai and initially prepared for India’s highly competitive engineering entrance route. According to his own website, he skipped the usual junior-college path to focus on the Joint Entrance Examination.
At the same time, he was building consumer applications. One of his early products converted tweets into attractive images. Shah says the tool gained tens of thousands of users and millions of monthly impressions before being acquired. TechCrunch reports that he sold the bot to social-media tool Hypefury.
The sale gave him both confidence and financial support to take a different path. Instead of continuing only toward an IIT admission, he moved to the United States and attended Arizona State University.
His first win came from solving a small, visible problem for real users—not from immediately building a large company.
The 40-Week Building Challenge
After moving to the United States, Shah challenged himself to build something new every week for 40 weeks. The routine helped him learn product development and user feedback.
During one of those weeks, he built a project initially called Any Context. The first version allowed people to interact with their Twitter bookmarks. It later developed into an open-source “second brain” product for organising knowledge collected across different apps.
Supermemory says this consumer version reached more than 50,000 users, stored millions of items and crossed 10,000 GitHub stars. These are company-reported figures from its funding announcement rather than independently audited usage data.
Operating the consumer product exposed a technical problem: AI applications needed better infrastructure to retain and retrieve context over time.
How Cloudflare Shaped the Supermemory Idea
Shah joined Cloudflare as an intern in 2024, working on AI and infrastructure, and later served in a developer-relations role. His website says he contributed to special projects and patent-related work.
His website also states that he later received a US O-1 visa, a category for people who meet specified extraordinary-ability criteria.
For Supermemory’s consumer app, Shah built components including a vector database, parsers and extraction tools. Businesses then asked to use the infrastructure in their products.
That interest helped turn Supermemory from a personal knowledge tool into an infrastructure company. Shah then left college to work on it full-time.
What Does Supermemory Do?
Large language models can answer complex questions, but an application may still struggle to remember a user’s history across multiple sessions or tools. Supermemory is designed to provide that missing memory layer.
| Input | What Supermemory is designed to do |
|---|---|
| Files, chats, emails and documents | Extract useful information and relationships |
| Previous user interactions | Retain relevant context over time |
| Multiple AI models or tools | Keep memory separate from one model provider |
| New questions or tasks | Bring relevant stored context back into the application |
The company now focuses on memory and continual learning for AI agents through an API, plugins and the Model Context Protocol.
In September 2026, Supermemory discontinued Company Brain and Nova, refunded charged customers and refocused on its core memory engine. On 25 September, the company released Company Brain as an open-source project, allowing developers to deploy, study and modify the discontinued product’s code independently.
Supermemory’s Funding Round
Supermemory announced its first funding round on 6 October 2025.
| Funding detail | Available information |
|---|---|
| Company’s announced amount | $3 million |
| TechCrunch’s reported amount | $2.6 million |
| Company’s round description | Pre-seed |
| TechCrunch’s round description | Seed |
| Lead investors named | Susa Ventures, Browder Capital and SF1.vc |
| Selected angel investors reported | Dane Knecht, Jeff Dean, Logan Kilpatrick, David Cramer, Theo Browne and Julian Weisser |
| Valuation | Not publicly disclosed |
Supermemory markets the round as $3 million pre-seed, while TechCrunch reported $2.6 million seed funding. The difference may reflect accounting, commitments or terminology, but no public explanation was found.
Reports also disagree about Shah’s age at the announcement. TechCrunch said 19; Shah wrote that he had turned 20 the previous month. The article therefore avoids using one disputed age as its central claim.
Reported Customers and Usage
At the time of funding, TechCrunch named Cluely, Montra, Scira, Composio’s Rube and Rets among Supermemory’s customers or users. The publication also reported work with a robotics company.
Supermemory’s current website says its infrastructure serves more than 100,000 organisations and processes over one trillion tokens each month. These are substantial claims, but they are company-published metrics and were not accompanied by audited customer or revenue data in the sources reviewed.
The company has not publicly disclosed annual revenue, profitability, retention or its funding valuation. A social-media claim that Supermemory is valued at $40 million was found, but no reliable primary confirmation was available, so that figure should not be treated as verified.
Challenges Behind the Success Story
Shah says he failed with multiple projects before Supermemory. The startup also moved from a consumer app to developer infrastructure and later discontinued two products to focus on its core engine.
Supermemory operates in a competitive field. TechCrunch identified companies such as Mem0, Letta and Memories.ai as participants in the AI-memory market. Larger model providers may also add deeper memory features to their own products.
The company must therefore prove that an independent memory layer can remain faster, more accurate and more flexible than alternatives while protecting sensitive user and enterprise data.
Lessons for Young Founders
- Small products create real skills: Shah’s early tools taught him distribution and user behaviour before he attempted a larger company.
- Consistency can outperform one big idea: The 40-week challenge created many chances to discover a useful problem.
- Open source can attract users and customers: Supermemory’s public project helped developers test the technology and contributed to early visibility.
- Follow the difficult technical problem: The infrastructure built for the consumer app became the foundation of the business.
- Changing direction is part of building: Supermemory’s product changes show that even funded startups continue to narrow their focus.
- Funding is not the finish line: Revenue, retention and dependable product performance will determine the company’s long-term outcome.
Is Dhravya Shah’s Story Already a Business Success?
Shah has sold teenage projects, worked at Cloudflare, built an open-source product and raised institutional funding as a solo founder.
However, Supermemory is still an early-stage company. Its official usage numbers are impressive, but revenue, valuation and profitability have not been publicly verified. The most accurate description is that Shah has built a promising AI-infrastructure startup with meaningful early traction—not that its commercial success is guaranteed.
Frequently Asked Questions
Dhravya Shah is a Mumbai-born software builder and the founder and CEO of Supermemory, an AI-memory infrastructure company based in San Francisco.
Supermemory provides memory and continual-learning infrastructure that helps AI applications retain, organise and retrieve context across users, sessions and data sources.
Supermemory officially announced a $3 million pre-seed round. TechCrunch reported the round as $2.6 million in seed funding, so both figures appear in public coverage.
No reliable source reviewed says that he enrolled at an IIT. He prepared for the JEE, later attended Arizona State University and then left college to work on Supermemory full-time. Calling him an “IIT dropout” would therefore be misleading.
No verified valuation has been publicly disclosed.
The Dhravya Shah success story is built on experimentation rather than a single breakthrough. An early acquisition, a 40-week building challenge, open-source adoption and work at Cloudflare all contributed to the idea behind Supermemory.
His journey shows that founders can start with small problems, learn from users and follow the difficult technical questions that appear along the way.
Supermemory now has funding, reported enterprise adoption and a clear focus on AI memory infrastructure. Its next challenge is converting that early momentum into reliable, long-term commercial performance.
Editorial Disclaimer
This article is based on publicly available company statements, founder profiles and media reports reviewed on. Funding totals, round labels and Shah’s reported age differ between sources, and those differences have been explained instead of presenting one version as undisputed fact.
Metrics such as user numbers, organisations served, tokens processed, GitHub growth and product performance originate from Supermemory or its founder unless stated otherwise. Startup information can change quickly. Readers should independently verify financial, operational and investment information before relying on it.
If you find an error or have updated supporting documents, please contact us, so we can review and correct the article.